
Avian
Avian solves slow AI inference with a private platform for open-source models. The result: a 3–10x faster, secure API with world-record performance and no data storage.
L'entreprise aujourd'hui
- Effectif
- 2 (2026-08-13)
- Followers
- 1’041 (2026-08-13)
- HQ
- New York, New York, United States
Croissance des effectifs
Basé sur les données LinkedIn.
Faits
- Secteur
- Data Infrastructure and Analytics
- Concurrents
- Hugging FaceMosaicML (Databricks)Cohere
- Clients
- No customers found
- Collaborateurs
- 2
- Followers
- 1’041
- Review créée
- Dernière vérification
Avian Review 2026: The Fastest Private AI Inference Put to the Test
- Special Feature: World record inference speed (351 TPS) on NVIDIA B200 hardware.
- Review & Critique: Excellent performance and privacy; however, high barriers to entry for dedicated instances.
- Ideal for: Companies with high data protection requirements and a need for real-time AI answers.
Introduction & Conclusion: Is Avian the Right Choice?
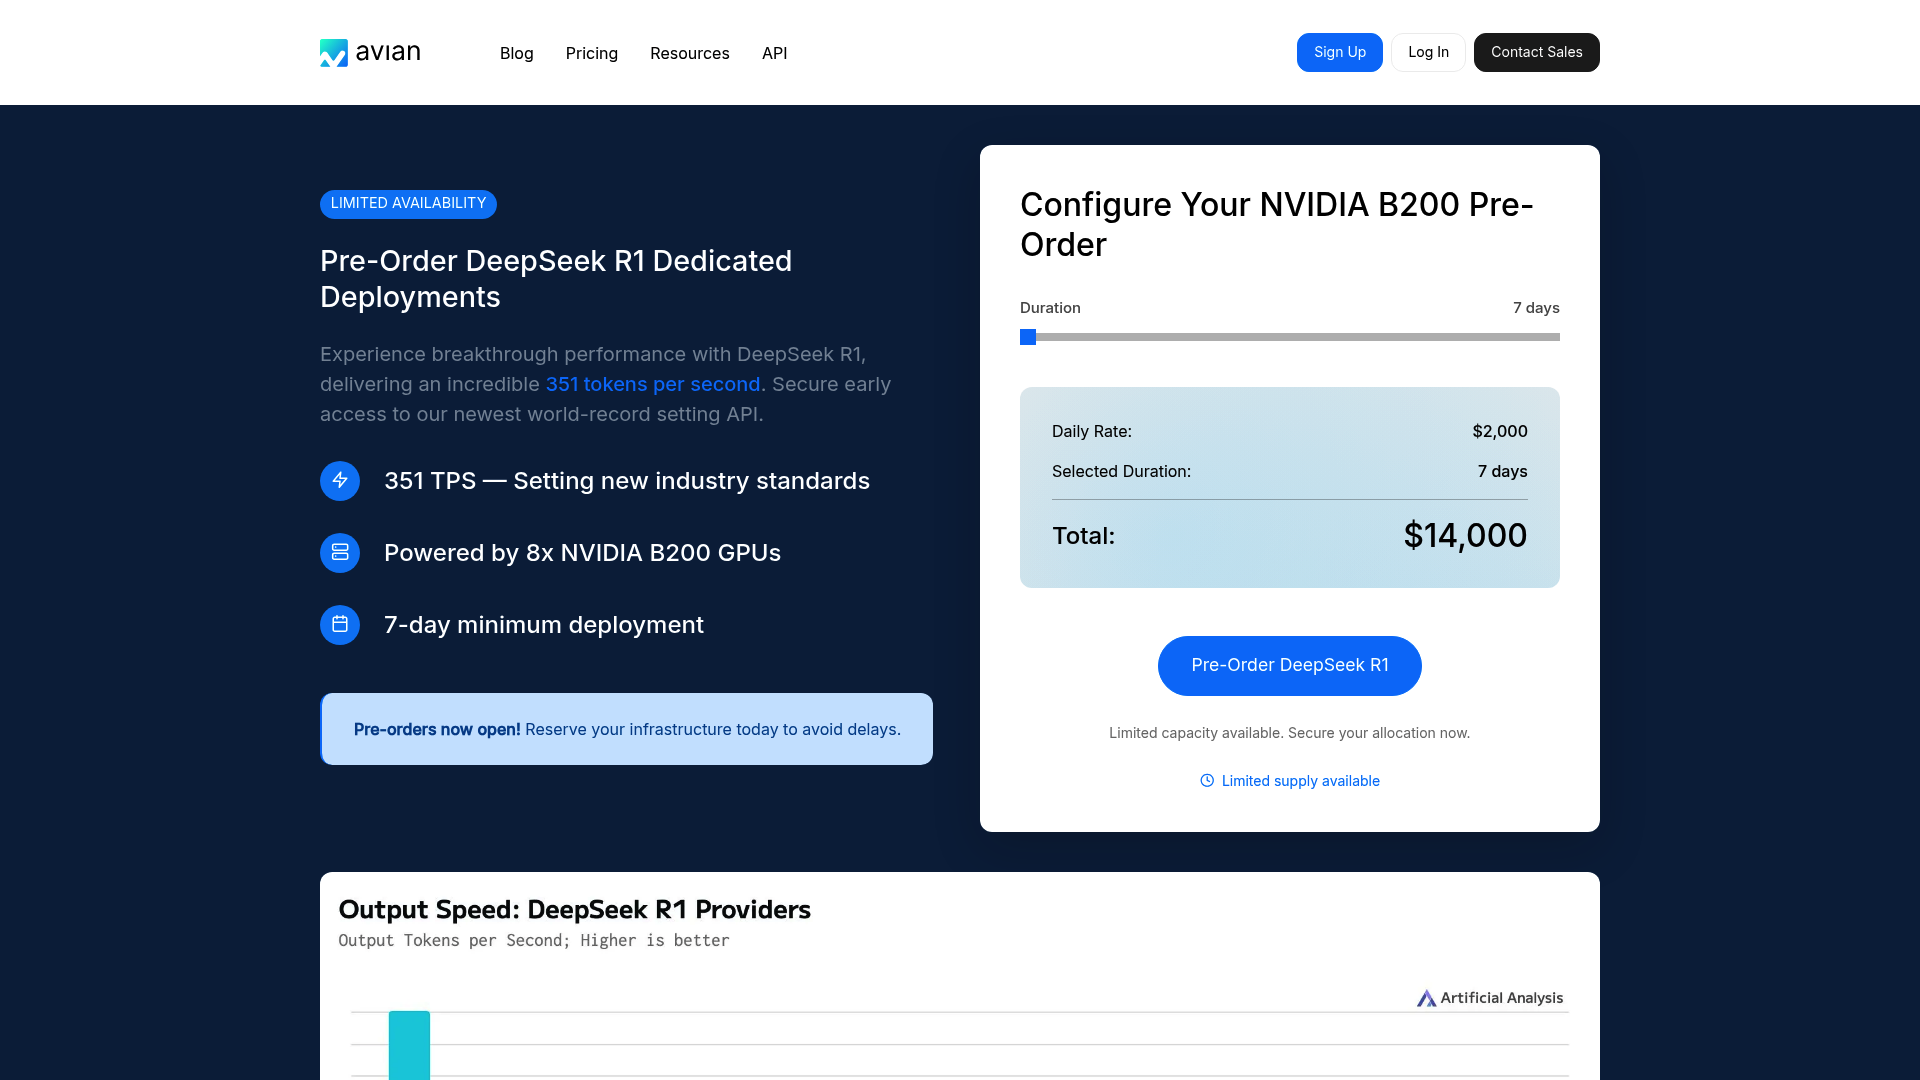
Avian is positioning itself in 2026 as the leading AI research lab for companies seeking maximum speed without compromising on data privacy. With an inference rate of 351 tokens per second for DeepSeek R1, Avian sets new standards. The solution is ideal for companies that want to run open-source models in a secure, SOC 2-compliant Azure environment, with dedicated hardware costs primarily tailored to enterprise budgets. Key Features of the AI Platform: Industry-Leading Inference Speed: At the heart of Avian is its optimization for NVIDIA Blackwell B200 GPUs. By leveraging TensorRT-LLM, the platform achieves speeds that are 3 to 10 times faster than the industry average. This enables near-zero-latency interactions, even with complex models like DeepSeek R1. Enterprise Data Privacy and Compliance: Unlike public API providers, Avian guarantees that no data is permanently stored. The infrastructure is SOC-2 certified and fully compliant with GDPR and CCPA. A special privacy mode for chats provides additional security in regulated industries. OpenAI-compatible API: Integration is incredibly easy, as Avian offers a fully compatible interface to the OpenAI standard. Existing workflows can be migrated to Avian within one minute to benefit from its increased speed and private hosting. Real-time customer support: Thanks to extremely low latency, AI agents can handle complex customer inquiries without any noticeable delay. Generative business intelligence: Avian enables specialized agents to analyze internal data sources without sensitive company data leaving the secure environment. Automated content creation: For media companies that need to produce high volumes of text in seconds, the 351 TPS rate offers a significant productivity advantage. Pricing and value analysis compared: Avian pursues a A dual-track pricing model aimed at professional users: On-demand usage: The entry-level price is approximately $10.00 per NVIDIA B200 hour for flexible workloads. Dedicated instances: For maximum performance, Avian offers dedicated deployments. These start at a daily rate of $2,000 (total: $14,000) with a minimum term of 7 days. Compared to competitors such as standard cloud providers, Avian offers a better price-performance ratio per generated token through specialized optimization, but requires a higher initial budget due to the minimum terms for dedicated hardware.
Actualités (90 jours)
Actualités
AVIAN was awarded as one of the Best Places to Work by Inc. Magazine for its focus on employee engagement and workplace culture. This recognition highlights AVIAN's commitment to its employees through strong communication, care, and recognition initiatives, reinforcing its values and vibrant culture.
Entreprise
Avian is an AI research studio that trains our own private large language models on Azure, Crimson MoE 70b and Mirage 34b. We provide Generative BI for Enterprise with privately hosted models based on Open Source foundation models. We train and create agents for each data connector using a mixture of experts architecture.
LinkedIn ↗